After the unprecedented achievements of ChatGPT and other foundation models in natural language processing and computer vision, robot foundation models became a major topic in 2023. Building a general-purpose robot—one that can competently and robustly perform many useful tasks in any home or office—is perhaps a shared ultimate goal of AI and robotics. Given the success of large models in language and vision, could the same paradigm help us reach that goal in robotics?
Recently, as I have evaluated startups, promoted projects, convinced myself and then tried to convince others, a series of questions has kept circling in my head. What is driving the growing excitement around embodied intelligence in 2023? Has there been an algorithmic breakthrough? Why have so many computer vision researchers moved into robot learning? Will collecting ever more data really work in robotics? LLMs and VLMs mainly advance perception and decision-making, but seem to have less impact on physical execution. How do we make execution reliable? Robotics has to confront shortcomings in actuation and demanding reliability requirements. Can the paradigm that succeeded in vision and language really transfer to this field?
A few days ago, while browsing Twitter, I found Nishanth J. Kumar's article, Will Scaling Solve Robotics? Perspectives from CoRL 2023. It asks whether training large neural networks on very large datasets is a viable route to solving robotics, and directly addresses many of my questions. I wanted to translate and share it immediately.
Much of this article draws on the debate at Deployable@CoRL2023. The participants are leading researchers in robot learning and control. The question was: 'Is scaling enough to deploy general-purpose robots?' Arguing the affirmative were Sergey Levine of UC Berkeley, Chelsea Finn of Stanford and Russ Tedrake of MIT. Arguing the negative were Stefan Schaal, Scott Kuindersma of Boston Dynamics and Emo Todorov of the University of Washington. Xiaolong Wang moderated. These are their debate roles, not an assertion that their research belongs exclusively to one camp.
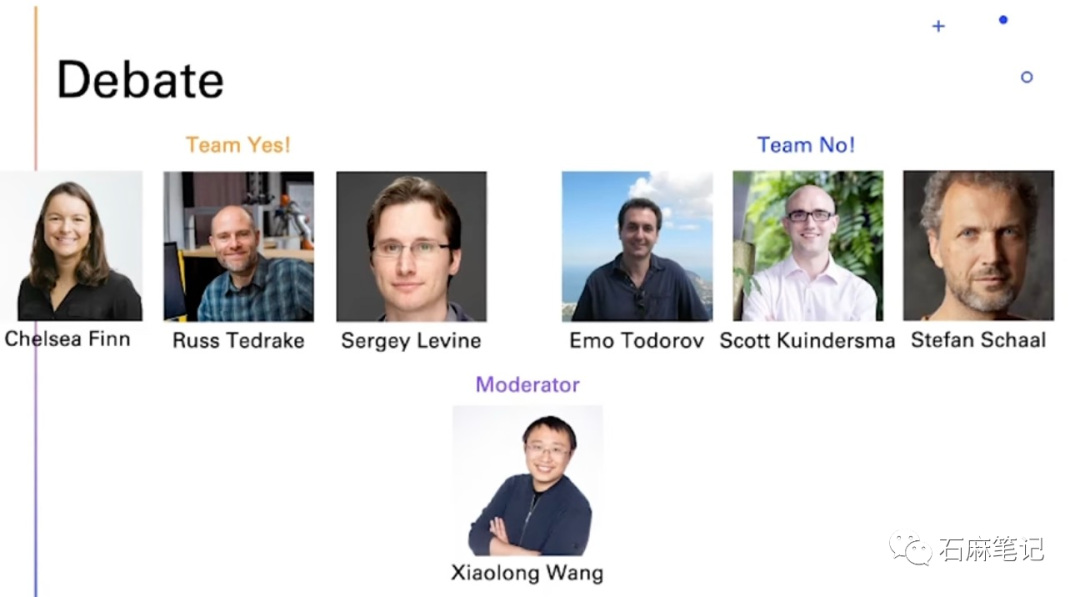
To make the discussion easier to read, I edited Kumar's account after listening to the debate video twice. The references include the YouTube and Bilibili recordings, along with his original article. The following is my Chinese article rendered into English, including my framing and reflections, rather than a substitute for Kumar's own original text.
Original article outline
Contents
↓
1. Introducing the participants
2. Arguments for scaling
3. Arguments against scaling as a complete solution
4. Other points of discussion
5. Some reflections
1. Introducing the participants
The affirmative participants are prominent figures in robot learning.
In this 2023 account, Sergey Levine is an associate professor in UC Berkeley's Department of Electrical Engineering and Computer Sciences and leads the Robotic Artificial Intelligence and Learning Lab, RAIL, within BAIR. The original introduction also identifies him as a Google Brain researcher and notes his participation in PaLM-E, RT-1 and RT-2. Editorial correction: the Chinese original says he earned his PhD at Berkeley under Pieter Abbeel. His official biography states that he earned his computer science PhD at Stanford in 2014, not Berkeley.
Chelsea Finn is an assistant professor of computer science and electrical engineering at Stanford. Her IRIS lab studies intelligence through robotic interaction at scale and is affiliated with the Stanford AI Lab, SAIL, and the machine learning group. She has also worked with Google Brain. She is interested in how robots and other agents develop broadly intelligent behavior through learning and interaction. She earned her computer science PhD at UC Berkeley, working with Sergey Levine, and her undergraduate degree at MIT. The positions described here provide the background to the 2023 debate.
Russ Tedrake is a professor of electrical engineering and computer science, aeronautics and astronautics, and mechanical engineering at MIT. He leads the Robot Locomotion Group and led MIT's entry in the DARPA Robotics Challenge. The original introduction also describes his directorship of the CSAIL Center for Robotics and his vice-presidential role at Toyota Research Institute. He earned his bachelor's degree in computer engineering at the University of Michigan, Ann Arbor, in 1999, and his EECS PhD at MIT in 2004 under Sebastian Seung. His work spans control, with a growing emphasis on applying systems-theoretic methods to robotic manipulation. This describes his role around the time of the debate, not a current employment update.
The negative participants bring extensive experience in control theory and model-based robotics.
Scott Kuindersma is introduced here as a research scientist at Boston Dynamics and a leader of the Atlas team. Previously, he was an assistant professor of engineering and computer science at Harvard, where he directed the Harvard Agile Robotics Lab, and a postdoctoral researcher in MIT's Robot Locomotion Group. His work uses optimal control to produce high-performance behavior in mobile robots.
Stefan Schaal is a German-American computer scientist working in robotics, machine learning, autonomous systems and computational neuroscience. He has been a professor at the University of Southern California in computer science, neuroscience and biomedical engineering, and a founding director of the Max Planck Institute for Intelligent Systems. His work on dynamic movement primitives, or DMPs, has been influential in robot learning. He is a towering figure in model-based control as well as an influential researcher in learning.
Emo Todorov is introduced in the original as an associate professor and director of the Movement Control Laboratory at the University of Washington. He helped establish optimal control as a framework for explaining biological movement and is a principal developer of MuJoCo. He earned his PhD at MIT, did postdoctoral work at UCL's Gatsby Computational Neuroscience Unit, and received a Sloan Research Fellowship in neuroscience in 2004. His research develops powerful optimal-control methods for complex movement in animals and robots. This is the historical background presented for the debate; the lab's current page is an archive rather than a current faculty listing.
2. Arguments for solving robotics by training large networks on large datasets
Scaling has worked remarkably well in vision and language, so it should also work well in robotics. Chelsea Finn points to unprecedented progress and emergent capabilities from models trained on enormous corpora, including GPT-4V and SAM. The basic training approach is general rather than unique to NLP or computer vision. Since it has proved effective in those areas, Finn’s argument is that it should work in other areas, such as robotics, too.
There are already signs that scaling could help robotics. Finn cites RT-2 as evidence that a single model trained with substantial robot data can generalize. Tedrake points to the surprising capabilities of diffusion policies. Levine discusses progress in building and deploying general-purpose navigation models. These are early results, with far smaller models and datasets than GPT-4, but they suggest that increasing scale may yield better robot learning.
Robotics should take advantage of the wave of data, compute and foundation models. The central idea is drawn from Rich Sutton’s influential essay, The Bitter Lesson: AI’s history shows relatively simple algorithms that scale with data always beating complex algorithms that do not scale. Editorial clarification: this is the article’s formulation; Sutton’s essay emphasizes computation and general methods such as search and learning, rather than a universal theorem about every dataset or algorithm. Karol Hausman's analogy is a technological wave. Whether we like it or not, more data and better compute will arrive. We can ride that wave or ignore it. For robotics, riding it means exploring large-scale pretraining for physical tasks, building on what succeeded in language and vision.
Large models are the best route we have to the common sense needed throughout robotics. Tedrake gives the example of putting a cup on a table. Even setting aside the difficulty of finding and localizing the cup, the task contains subtleties. A cluttered table may require clearing space. A dropped cup must be retrieved and repositioned. A cup containing liquid must be handled without spilling. Such details occur frequently and can determine success or failure. The affirmative argument is that training on large quantities of experience could help robots reason through these situations.
3. Arguments against scaling as a complete solution to robotics
Interestingly, few participants reject the theoretical possibility that scaling could work in robotics. Most objections fall into two categories: first, that it is simply impractical; second, that even if it works to some extent, it may not truly solve robotics.
(1) The approach is simply impractical
We do not have robot data at internet scale, nor a clear way to obtain it. This is the central problem in discussions of large-scale robot learning. The original puts this bluntly: the internet has enormous amounts of vision and language data, but no robot data at all. Vision and language benefit from an incredible data flywheel: billions of people connecting to and using the internet. Collecting an enormous robot dataset requires time, money and collaboration, and may still fall far short of those corpora. Since important capabilities in other domains emerged only at scale, insufficient data could make this scaling approach hopeless in robotics. Editorial clarification: the original says there is no robot data on the internet at all. Public robot datasets existed in 2023; the issue is their scale, diversity and action coverage compared with web image and text data.
Robots have different embodiments. A command sent to Boston Dynamics' Spot differs from a command sent to a KUKA iiwa arm. Robots vary in shape, size and morphology, so data may need to be collected or adapted for different robot types, making the collection problem harder.
Human environments vary enormously. A truly general-purpose robot must operate in the homes, factories and offices where people want to use it. Collecting data from every possible space is impractical. We can sample some environments and rely on generalization for the rest, but we do not know how much data is needed for that generalization to emerge. The required amount may itself be impractically large.
Training on such a dataset could also demand enormous compute. Foundation-model training is expensive in money and energy. The original article cites reported estimates of more than US$100 million and 50 million kilowatt-hours for GPT-4-related training, and asks whether robot models might require another order of magnitude or more. These figures are not independently verified official measurements, and should not be treated as established costs for GPT-4V specifically. The underlying question remains: such resources are beyond an academic lab's budget—who can afford the required scale?
(2) Even matching the success of vision and language may not solve robotics
The 99.x% reliability problem. Google robotics researcher Vincent Vanhoucke makes a provocative assertion: most robot learning methods cannot be deployed for any practical task, because real industrial and household applications typically demand reliability above 99.x%, beyond what most learned robot systems demonstrate. The discussion contrasts that requirement with most academic results topping out at 80% success. The remaining gap is qualitatively difficult: the effort required to go from 99% toward 100% increases exponentially, and may require an entirely new set of techniques beyond scaling. The assertion of exponentially increasing effort expresses the difficulty, rather than a proven universal scaling law or a success-rate figure applicable to every paper.
Existing vision and language models also fall short of such reliability, but can still be useful. The article argues that ChatGPT’s occasional confident nonsense does not have a large negative impact, while hardware failures cost far more than software failures and thus demand much higher reliability. Therefore, even reaching the present achievements of NLP would not automatically make a robot deployable. The relevant reliability requirement depends on the task; software errors can also have serious consequences, so the point is about the physical setting and its failure costs rather than all software being harmless.
Autonomous driving offers a cautionary example. Companies such as Tesla have tried to achieve Level 5 autonomy by training an end-to-end large model on huge datasets, with the necessary money, compute and data from deployed cars. The original discussion describes data collection from more than 100,000 vehicles. Yet in 2023, that had not produced Level 5 autonomy. The approach could handle many situations, but was still far from 99.x% reliability, in the article’s assessment. This is a historical argument about deployment limits, not a current fleet-size report.
The discussion also suggests that Tesla's approach performed much worse than the more modular systems of Waymo or Cruise, raising doubts about whether scale alone overcomes the reliability problem. That is an argument made in the 2023 discussion, not a controlled comparison of equivalent deployments or a current assessment of those companies. Autonomous driving is one particular physical application, so its experience gives reason to question scaling as a complete robotics solution, especially over the medium term.
Long-horizon tasks compound the challenge. Making tea involves a sequence of operations, such as boiling water, pouring and adding a tea bag. Imagine a policy sending torque commands to seven motors at 40 Hz for five minutes. That is 7 × 40 × 60 × 5 = 84,000 individual motor commands. Add mobility or more arms and the system becomes more complex. Errors can accumulate over time, as they can in an LLM generating a long story. The original argues that even LLMs able to produce long passages cannot yet write entirely coherent novels or stories, because small prediction deviations accumulate into large departures over long timescales, so even a capable local predictor may struggle with a lengthy task. The arithmetic illustrates how many outputs are involved; it does not imply that the commands are independent trials or that every tiny deviation necessarily causes failure. Feedback and replanning matter.
4. Other points of discussion
Deploying learned systems robustly
A common objection to learned robotics is the lack of theoretical guarantees and interpretability. Neural networks remain difficult to understand completely, and their outputs under unfamiliar conditions are hard to guarantee. Classical planning and control methods often offer guarantees under explicit assumptions, which can be valuable for safety.
Levine responds that many conventional control guarantees do not address the failures that matter most in real applications. His example is a truck with a sky painted on its rear, confusing an autonomous vehicle's perception—not the comparatively straightforward task of controlling the car along a straight line. The challenge is dealing with the world's complexity, not only stabilizing the low-level controller.
Kuindersma describes deploying RL-based controllers on Boston Dynamics robots and building confidence through rigorous simulation and real-world testing. The participants value theoretical guarantees and interpretability, and encourage further research, but do not conclude that their absence makes robust deployment impossible. Testing-based confidence and formal guarantees are different forms of evidence.
Deploying human–machine teams
Todorov points out that successful systems such as Codex and ChatGPT work well only because people interact with them and clean up their outputs. In his example, Codex is intended as intelligent autocomplete for a programmer, rather than a way to generate runnable, error-free code directly; the human–machine team is more efficient than either working alone. These models need not meet the 99.x% threshold because people can correct problems during use. Human correction changes the performance requirement on the model itself. His point is that people can tolerate and fix some mistakes, whereas physical processes do not forgive an incorrect command in the same way.
Finn broadly agrees that all successfully deployed and useful machine learning systems require human participation and could also be part of deployed robot learning. Human involvement is harder to arrange in robotics than in some software applications, but she argues it can solve robotics’ 99.x% problem. It does not automatically guarantee 99.x% reliability without an effective intervention mechanism.
Scaling may not require collecting all the data in the real world
There are ways to address the real-data bottleneck. Fast, realistic simulators might let us train policies in simulation and transfer them to reality. Existing visual, language and video data might also provide much of the prior knowledge, with a relatively small amount of robot experience added. RT-2 illustrates how internet-scale vision–language pretraining combined with robot action training can support robot tasks. The original summarizes this as fine-tuning on a smaller robot dataset; RT-2's published method co-fine-tunes web and robot data.
Combining model-based control and learning
Kuindersma argues that model-based control can help learning, and vice versa. He firmly believes combining learning with classical techniques is the best route to reliable real-world systems over the short to medium term. Research has shown that such combinations can enable capabilities neither approach provides alone. Many participants see this middle route as promising. Over the longer term, pure learning—or an approach not yet discovered—might turn out to be the answer.
Pursuing large-scale learning
Despite disagreement about whether scaling can solve everything, most participants see it as a promising research direction. Even an incomplete solution could advance problems that have long resisted progress. Tedrake also notes that pursuing it carefully may teach us about general-purpose robotics, current learning algorithms and why they work as well as they do.
Do not neglect classical control and other approaches
Even strong supporters of scaling do not think everyone should work on it. Putting the entire robot learning community's effort into one approach would be risky, particularly when there are reasons to doubt its completeness. Classical robotics has already enabled substantial, reliable deployments. Advancing those methods or combining them with learning may be the right route, especially in the short to medium term.
Pay more attention to mobile manipulation and usable systems
Vanhoucke observes that most CoRL 2023 papers stay within tabletop manipulation. There are difficult problems there, but mobility adds complexity, particularly when the camera view changes. Levine also observes that much of the excitement and adoption around LLMs comes from ease of use. Nonexperts can prompt them without understanding training details or performing elaborate setup. Robot learning methods are far from that experience: using them often requires extensive knowledge of their internals and significant setup. Making them easier to use and more broadly applicable could improve adoption and help scaling.
Be more candid about what does not work
Robot learning papers often underreport negative results, causing needless repetition of failed efforts. Patterns in repeated failures could also provide new insight into algorithms. Researchers currently have little incentive to report such outcomes, but many participants support creating better incentives.
Try something entirely new
Some participants note that current approaches, whether learned or classical, remain unsatisfactory in several ways. A quite different family of methods might eventually solve the problem. Continued exploration beyond today's familiar alternatives is therefore important.
5. Some reflections
Over the past six months of 2023, China's investment, robotics and academic communities have been swept up in enthusiasm, willingly or otherwise. For investors, embodied intelligence is unquestionably the hottest of the few remaining investment themes in 2023. People from entertainment, consumer and Web3 investing are rushing in, adopting the label as supposedly undiscovered startups circulate through WeChat and brief meetings. The robotics industry, still near a low point in 2022, has suddenly found itself riding a wave; some quick-moving companies have recast themselves as embodied AI or humanoid businesses. In academia, the assistant professors at Tsinghua, Peking University and Shanghai Jiao Tong may feel the pressure most. I have heard of an investor putting RMB50,000 onto a cafe membership near Tsinghua just to meet professors. Even robot learning researchers in North America are repeatedly approached by Chinese investors. Of course, I am one of those investors too
[Watermelon reaction emoji: watching the spectacle]
.
Dialogue between people with different backgrounds is valuable. Sharing information and knowledge can help us understand what general-purpose robots might make possible. But in this restless moment, how do we find the approximately right early-stage investment? Strong teams command high valuations; discussion of real deployment brings sighs; promoting a project internally raises its own problems. After a month of weekly trips, often out and back on the same day, this exhausted investor decided to return to being the author of a public account.
I hold one firm view about general-purpose robotics. Academic groups and large companies may explore without being responsible for delivering a final product. A startup cannot survive without thinking about delivery. A robot is fundamentally a blue-collar worker: its value comes from completing particular tasks. A startup that talks only about brilliant algorithms, neglecting hardware, system integration and the ability to deliver a product, is destined to fail in robotics.
Many scientific problems remain on the road to general-purpose robots. In my view at the time of writing, this is not something we will see fully realized in two or three years. Before our imagined general-purpose robot can exist, it first has to be a functioning robot. What do I mean? Among decision-making, perception and execution, I see execution as the largest bottleneck. It requires working through individual applications in detail. Customers will not pay without that practical delivery capability. Physical products allow little tolerance for failures in the task, which may be the biggest difference between embodied AI and software-only AI.
Everyone in this wave seems to be aiming for a general-purpose robot—which does not necessarily mean a general-purpose humanoid. But that goal is more like a North Star. Anyone who only gazes at the stars is destined to become cannon fodder. The people building robots need to remain grounded while keeping the distant goal in sight. As investors and founders in this field, I hope we can find a place to stand between those two perspectives.
References
Original article
https://nishanthjkumar.com/Will-Scaling-Solve-Robotics-Perspectives-from-CoRL-2023/ The author's current address for this article: https://nishanthjkumar.com/blog/2023/Will-Scaling-Solve-Robotics-Perspectives-from-CoRL-2023/
Debate recording on YouTube
https://www.youtube.com/watch?v=pGjzxdD2Sa4&list=PLtF7v_W_CG5oG_lhI9tA1g4dPJKBOWDsA&index=15
Debate recording on Bilibili
Other references
https://groups.csail.mit.edu/locomotion/russt.html
https://scottk.seas.harvard.edu/
https://homes.cs.washington.edu/~todorov/